Limitations
Contents
Limitations#
Cutting down on overfitting#
A decision tree chooses its split thresholds based only on the training data. Left unconstrained, it keeps splitting until it fits the noise, carving the feature space into tiny rectangular regions that hold only a handful of points. That is overfitting. We regularize a tree by restricting its freedom through hyperparameters:
Maximum depth (
max_depth) caps how many levels of splits the tree can make. A tree of depth 2 makes one split at the root node and one or two splits at level one.Minimum samples to split (
min_samples_split) is the number of samples a node must contain before it is allowed to split. The algorithm checks the node before splitting it.Minimum samples per leaf (
min_samples_leaf) is the number of samples each child must contain. The algorithm checks the candidate child nodes before making a split.Maximum leaf nodes (
max_leaf_nodes) sets an upper limit on the total number of leaves.
Exercise
How to tweak (increase of decrease) the hyperparameters in order to relevantly perform a regularization?
Check your answers
Hyperparameters with minimum in their name regularize the tree when increased, while those with maximum in their name regularize it when decreased.
Orthogonal cuts#
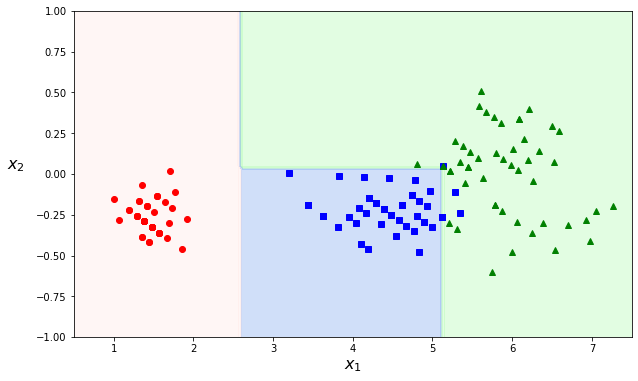
As the decision trees work with threshold values, the boundaries are always perpendicular to an axis. This works well if the data is ‘by chance’ aligned with the axes. This ‘feature’ makes decision trees sensitive to rotation. If we rotate the dataset used in the example above, we can see it changes decision boundaries:
angle = np.pi / 180 * 20
rotation_matrix = np.array([[np.cos(angle), -np.sin(angle)], [np.sin(angle), np.cos(angle)]])
Xr = X.dot(rotation_matrix)

tree_clf_r = DecisionTreeClassifier(random_state=42)
tree_clf_r.fit(Xr, y)

plot_decision_boundary(tree_clf_r, Xr, y, axes=[0.5, 7.5, -1.0, 1])
Instability#
Not only rotated data samples, decision trees can also drastically change with only minimal modification in the data. Removing one data point in the dataset above can lead to very different decision boundaries:
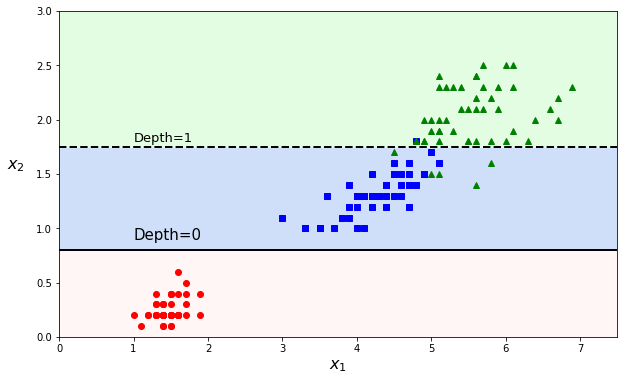
Instability will change future predictions and is quite a bad feature (bug) from a machine learning algorithm. How to circumvent this intrinsic instability? This is what we will cover in the next section!